Corpus
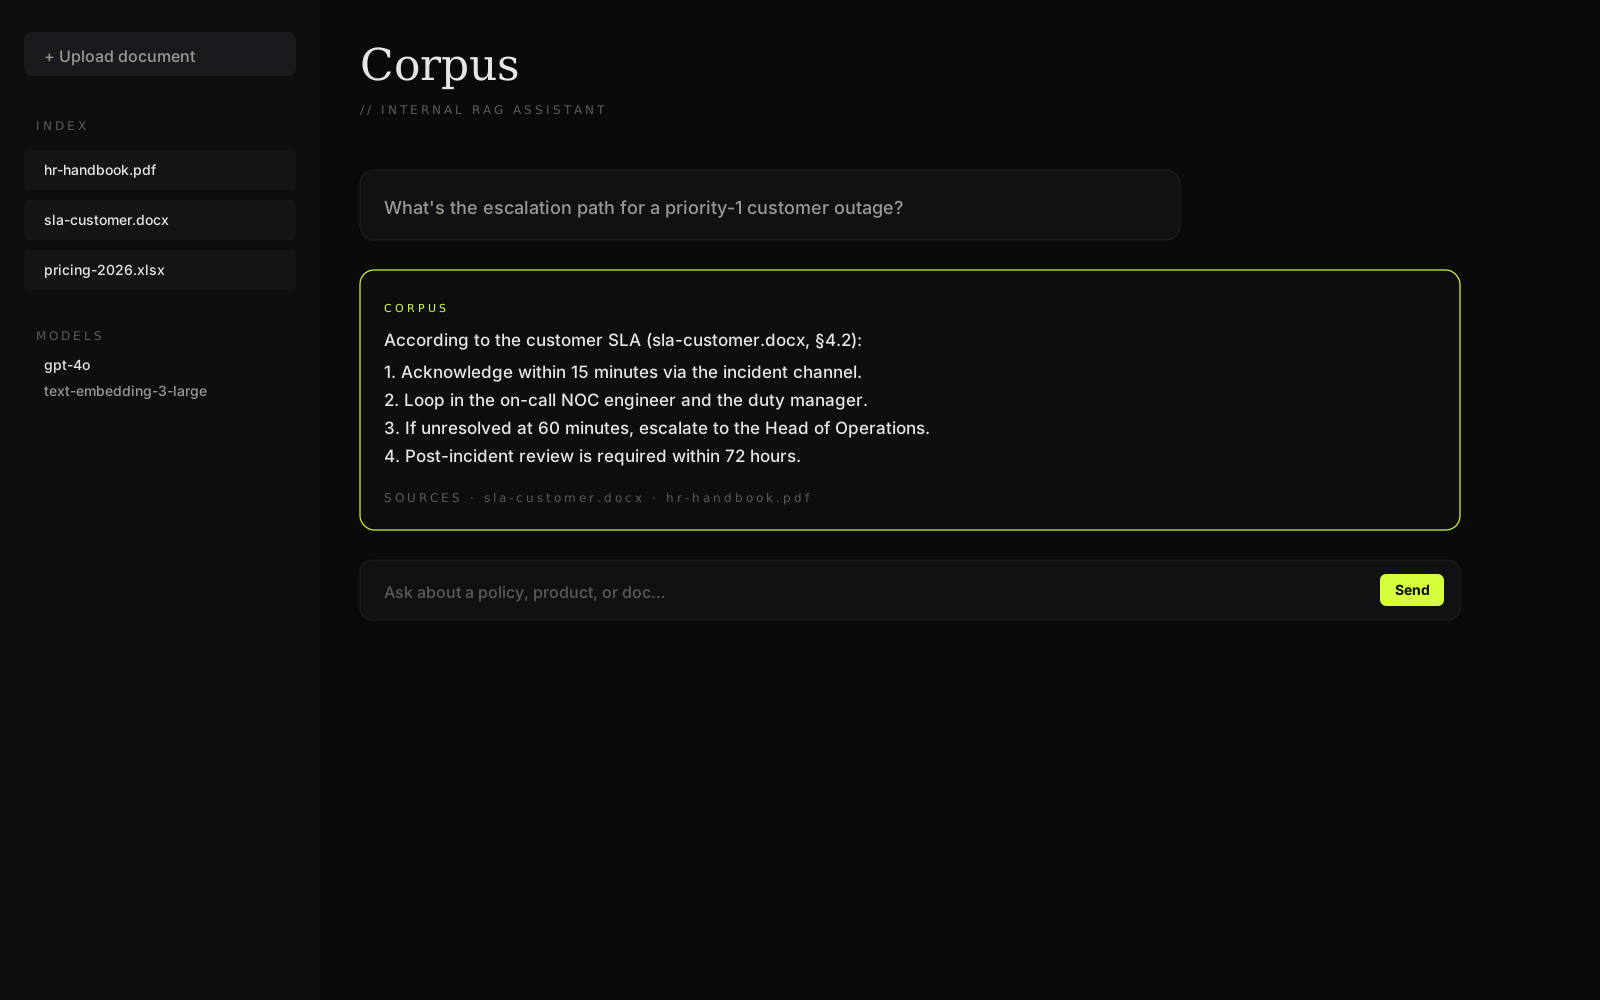
Internal RAG chatbot over company documentation — Streamlit + GPT-4o + FAISS.
- Embedding model
- text-embedding-3-large
- Answer model
- GPT-4o
- Vector store
- FAISS
- Doc types
- PDF / DOCX / XLSX / TXT
Solo engineer
- Python
- Streamlit
- OpenAI
- FAISS
- RAG
- LangChain
Problem
Internal staff needed a fast way to query company documentation — policies, product specs, scattered PDFs and spreadsheets — without pinging the author of each document every time.
Approach
Streamlit front-end wired to a RAG pipeline: documents are ingested (PDF / DOCX / XLSX / TXT), chunked with token-based overlap, embedded with OpenAI text-embedding-3-large, stored in FAISS, and queried against GPT-4o with session-level conversation history. Operators can rebuild / inspect the index from the sidebar.
Outcome
Working internal assistant. Used as the prototype that informed a later, more hardened deployment.
Why FAISS, not a managed store
The corpus is small enough (hundreds of documents, not millions) that a local FAISS index gives near-zero latency and no recurring infra cost. Re-indexing runs from the operator UI in seconds.
What I'd change for v2
Move chunking and embedding to a scheduled pipeline rather than on-upload, add eval harness for answer quality, switch secrets to environment variables, and ship with a Dockerfile for reproducible deploys.